
Enterprise Copilots & Assistants
Copilots embedded in the tools your teams already use, grounded in your own data, with permission-aware retrieval so each user only ever sees what they are entitled to.

Product Discovery & Solution Architecture
We scope the use case, pick the model and retrieval approach, settle build versus buy, and define the accuracy, latency, and cost targets the product has to hit before any code is written.

Custom LLM Application Development
Full-stack product engineering around the model: orchestration, prompt and context layer, APIs, web and mobile interfaces, and the state handling that keeps multi-step work resumable.

Data & Retrieval Engineering
Corpus-tuned chunking, hybrid search, reranking, and permission-aware retrieval, with every answer carrying the source passage it was grounded in.

Model Layer, Fine-Tuning & Routing
We benchmark your workload across models, fine-tune only where it pays for itself, and route requests by task so quality and cost per request are both under control.

Agentic Workflows & Tool Integration
Typed, idempotent, permissioned tools with bounded loops and human checkpoints on consequential actions, so the product can act without acting unpredictably.

Enterprise Integration & Deployment
We wire the product into the systems it has to live with, then ship it on CI/CD with staged rollouts, feature flags, and a rollback path that actually works.

Evaluation, Observability & Continuous Improvement
Golden datasets and regression suites in CI, traces across prompts, retrieved context and tool calls, drift alerts, and a feedback loop that turns real usage into the next release.
Copilots embedded in the tools your teams already use, grounded in your own data, with permission-aware retrieval so each user only ever sees what they are entitled to.

Products that read contracts, claims, policies, and reports at scale, returning structured output with citations auditors and reviewers can actually check.

Products where the AI does the work rather than describing it: multi-step execution across your systems, with bounded tool use and human approval where it matters.

Multi-tenant SaaS built around a model from day one, with per-tenant data isolation, usage metering, and unit economics that still work at scale.

Products that score, forecast, and flag, combining models with your business rules so every output comes with a reason a reviewer can defend.

Chat and voice products engineered for real conversations: low latency, interruption handling, context that survives the session, and clean escalation to a human.
Products touching payments, KYC, and customer records, built with audit-ready logging, deterministic business rules, and explainable output. See our AI agents for banking.
Clinical documentation and patient-facing products engineered with PHI-aware data handling, strict retrieval scoping, and clinician review built into the workflow.
Search, recommendation, and support products that have to answer in milliseconds at peak traffic, so caching and cost per request are engineered in, not patched later.
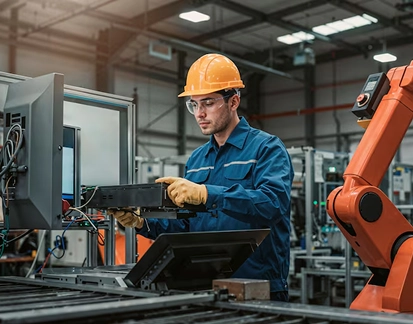
Quality inspection, maintenance, and planning products wired into MES and SCADA data, built to run reliably at the edge as well as in the cloud.
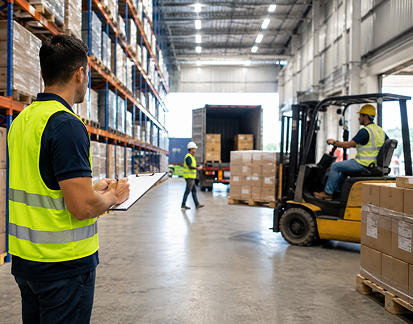
Planning and exception-handling products that act across TMS, WMS, and carrier APIs, with hard limits on what an automated decision is allowed to move.
Claims and underwriting products that extract structured data from messy documents and show the evidence behind every recommendation they make.
One team owns the model layer, the retrieval layer, the application, and the deployment pipeline, so nothing falls into the gap between a data team and a product team.
We design for the load, the failure modes, and the audit trail from the first sprint, rather than retrofitting a prototype that was never meant to carry real traffic.
Your AI product has to live inside existing systems. We handle that through enterprise AI integration, from identity and permissions to legacy data sources.
Model routing, caching, batching, and token budgets per request, so your cost per user is a number you can forecast before the invoice arrives.
Guardrails, PII handling, access scoping, and decision logging engineered in from the start, mapped to your AI governance requirements.
Every release passes an evaluation suite before it ships, and real usage feeds the next one, so the product gets measurably better instead of quietly drifting.






Weeks 1-2. We pin down the use case, the model and retrieval approach, the integration surface, and the accuracy, latency, and cost targets the product must hit to be worth shipping.
Weeks 2-4. We prepare your corpus, build the retrieval pipeline with permission-aware scoping, and create the golden dataset every later release is measured against.
Weeks 3-8. Orchestration, prompt and context engineering, tool integration, APIs, and the application interface, built in two-week increments you can review as they land.
Weeks 8-10. Regression suites in CI, adversarial and edge-case testing, guardrail tuning, load testing, and cost and latency optimization against the targets set in week one.
Weeks 10-12. Staged rollout behind feature flags, monitoring and alerting live from day one, runbooks, and handover sessions for the teams who will own it.
Models change, data drifts, and usage patterns move. We monitor quality, cost, and latency in production and ship improvements on a regular cadence. Our AI pilot to production services keep the product stable as it scales.


